1. 概述
1.1. 压缩的好处和坏处
压缩的优点:以减少磁盘IO、减少磁盘存储空间。
压缩的缺点:增加CPU开销。
1.2. 压缩的原则
1)运算密集型的Job,少用压缩
2)IO密集型的Job,多用压缩
2. MR支持的压缩编码
2.1. 压缩算法对比介绍
| 压缩格式 | Hadoop自带? | 算法 | 文件扩展名 | 是否可切片 | 换成压缩格式后,原来的程序是否需要修改 |
| DEFLATE | 是,直接使用 | DEFLATE | .deflate | 否 | 和文本处理一样,不需要修改 |
| Gzip | 是,直接使用 | DEFLATE | .gz | 否 | 和文本处理一样,不需要修改 |
| bzip2 | 是,直接使用 | bzip2 | .bz2 | 是 | 和文本处理一样,不需要修改 |
| LZO | 否,需要安装 | LZO | .lzo | 是 | 需要建索引,还需要指定输入格式 |
| Snappy | 是,直接使用 | Snappy | .snappy | 否 | 和文本处理一样,不需要修改 |
2.2. 压缩性能的比较
| 压缩算法 | 原始文件大小 | 压缩文件大小 | 压缩速度 | 解压速度 |
| gzip | 8.3GB | 1.8GB | 17.5MB/s | 58MB/s |
| bzip2 | 8.3GB | 1.1GB | 2.4MB/s | 9.5MB/s |
| LZO | 8.3GB | 2.9GB | 49.3MB/s | 74.6MB/s |
关于snappy的压缩,可以参考此网址:snappy | A fast compressor/decompressor
Snappy是一个压缩/解压库。 它的目标不是最大压缩,或与任何其他压缩库兼容; 相反,它的目标是非常高的速度和合理的压缩。 例如,与zlib的最快模式相比,Snappy在大多数输入中都快了一个数量级,但是压缩后的文件却大了20%到100%。 在64位模式的单核core i7处理器上,Snappy压缩速度约为250 MB/秒,解压速度约为500 MB/秒。
3. 压缩方式选择
压缩方式选择时重点考虑:压缩/解压缩速度、压缩率(压缩后存储大小)、压缩后是否可以支持切片。
3.1. Gzip压缩
优点:压缩率比较高;
缺点:不支持Split;压缩/解压速度一般;
3.2. Bzip2压缩
优点:压缩率高;支持Split;
缺点:压缩/解压速度慢。
3.3. Lzo压缩
优点:压缩/解压速度比较快;支持Split;
缺点:压缩率一般;想支持切片需要额外创建索引。
3.4. Snappy压缩
优点:压缩和解压缩速度快;
缺点:不支持Split;压缩率一般;
3.5. 压缩位置选择
压缩可以在MapReduce作用的任意阶段启用。
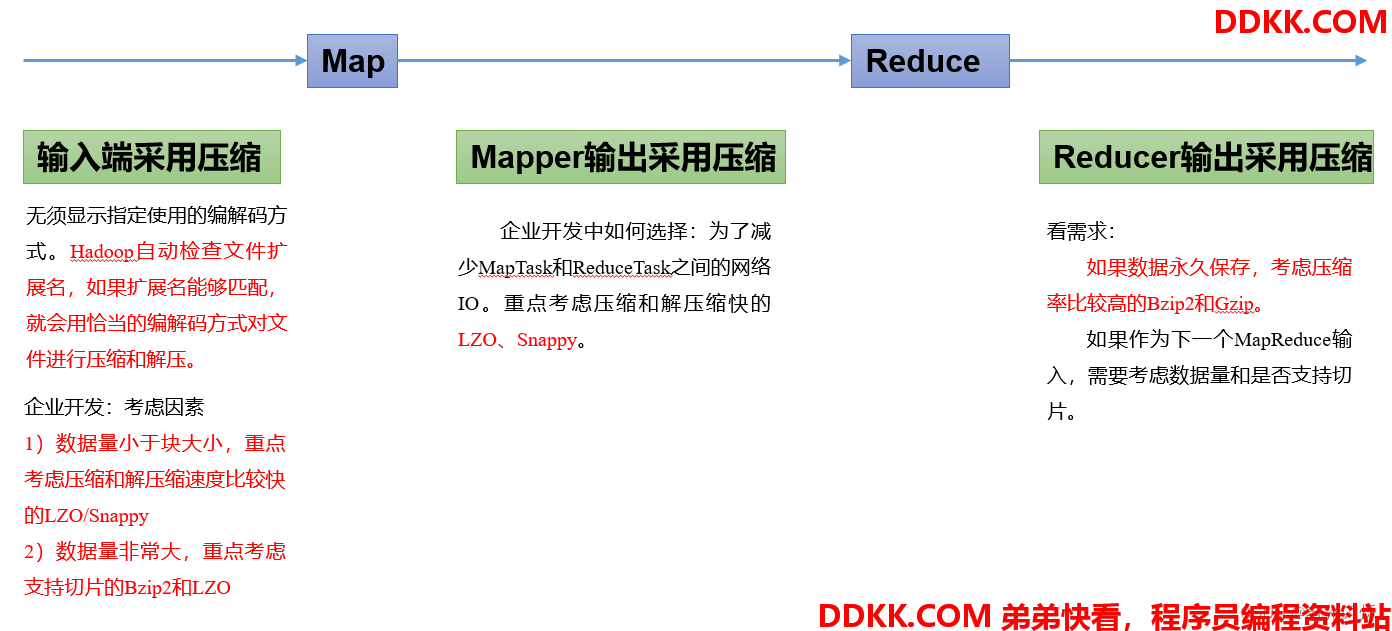
4. 压缩参数配置
1)为了支持多种压缩/解压缩算法,Hadoop引入了编码/解码器
| 压缩格式 | 对应的编码/解码器 |
| DEFLATE | org.apache.hadoop.io.compress.DefaultCodec |
| gzip | org.apache.hadoop.io.compress.GzipCodec |
| bzip2 | org.apache.hadoop.io.compress.BZip2Codec |
| LZO | com.hadoop.compression.lzo.LzopCodec |
| Snappy | org.apache.hadoop.io.compress.SnappyCodec |
2)要在Hadoop中启用压缩,可以配置如下参数
| 参数 | 默认值 | 阶段 | 建议 |
| io.compression.codecs(在core-site.xml中配置) | 无,这个需要在命令行输入hadoop checknative查看 | 输入压缩 | Hadoop使用文件扩展名判断是否支持某种编解码器 |
| mapreduce.map.output.compress(在mapred-site.xml中配置) | FALSE | mapper输出 | 这个参数设为true启用压缩 |
| mapreduce.map.output.compress.codec(在mapred-site.xml中配置) | org.apache.hadoop.io.compress.DefaultCodec | mapper输出 | 企业多使用LZO或Snappy编解码器在此阶段压缩数据 |
| mapreduce.output.fileoutputformat.compress(在mapred-site.xml中配置) | FALSE | reducer输出 | 这个参数设为true启用压缩 |
| mapreduce.output.fileoutputformat.compress.codec(在mapred-site.xml中配置) | org.apache.hadoop.io.compress.DefaultCodec | reducer输出 | 使用标准工具或者编解码器,如gzip和bzip2 |
5. 压缩实操案例
5.1. Map输出端采用压缩
即使MapReduce的输入输出文件都是未压缩的文件,仍然可以对Map任务的中间结果输出做压缩,因为它要写在硬盘并且通过网络传输到Reduce节点,对其压缩可以提高很多性能,这些工作只要设置两个属性即可,具体代码设置如下。
1)Hadoop源码支持的压缩格式有:BZip2Codec、DefaultCodec
import java.io.IOException;
import org.apache.hadoop.conf.Configuration;
import org.apache.hadoop.fs.Path;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.io.compress.BZip2Codec;
import org.apache.hadoop.io.compress.CompressionCodec;
import org.apache.hadoop.io.compress.GzipCodec;
import org.apache.hadoop.mapreduce.Job;
import org.apache.hadoop.mapreduce.lib.input.FileInputFormat;
import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;
public class WordCountDriver {
	public static void main(String[] args) throws IOException, ClassNotFoundException, InterruptedException {
		Configuration conf = new Configuration();
		// 开启map端输出压缩
		conf.setBoolean("mapreduce.map.output.compress", true);
		// 设置map端输出压缩方式
		conf.setClass("mapreduce.map.output.compress.codec", BZip2Codec.class,CompressionCodec.class);
		Job job = Job.getInstance(conf);
		job.setJarByClass(WordCountDriver.class);
		job.setMapperClass(WordCountMapper.class);
		job.setReducerClass(WordCountReducer.class);
		job.setMapOutputKeyClass(Text.class);
		job.setMapOutputValueClass(IntWritable.class);
		job.setOutputKeyClass(Text.class);
		job.setOutputValueClass(IntWritable.class);
		FileInputFormat.setInputPaths(job, new Path(args[0]));
		FileOutputFormat.setOutputPath(job, new Path(args[1]));
		boolean result = job.waitForCompletion(true);
		System.exit(result ? 0 : 1);
	}
}
2)Mapper保持不变
import java.io.IOException;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.LongWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Mapper;
public class WordCountMapper extends Mapper<LongWritable, Text, Text, IntWritable>{
	Text k = new Text();
	IntWritable v = new IntWritable(1);
	@Override
	protected void map(LongWritable key, Text value, Context context)throws IOException, InterruptedException {
		// 1 获取一行
		String line = value.toString();
		// 2 切割
		String[] words = line.split(" ");
		// 3 循环写出
		for(String word:words){
			k.set(word);
			context.write(k, v);
		}
	}
}
3)Reducer保持不变
import java.io.IOException;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Reducer;
public class WordCountReducer extends Reducer<Text, IntWritable, Text, IntWritable>{
	IntWritable v = new IntWritable();
	@Override
	protected void reduce(Text key, Iterable<IntWritable> values,
			Context context) throws IOException, InterruptedException {
		int sum = 0;
		// 1 汇总
		for(IntWritable value:values){
			sum += value.get();
		}
         v.set(sum);
         // 2 输出
		context.write(key, v);
	}
}
5.2. Reduce输出端采用压缩
基于WordCount案例处理
1)修改驱动
import java.io.IOException;
import org.apache.hadoop.conf.Configuration;
import org.apache.hadoop.fs.Path;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.io.compress.BZip2Codec;
import org.apache.hadoop.io.compress.DefaultCodec;
import org.apache.hadoop.io.compress.GzipCodec;
import org.apache.hadoop.io.compress.Lz4Codec;
import org.apache.hadoop.io.compress.SnappyCodec;
import org.apache.hadoop.mapreduce.Job;
import org.apache.hadoop.mapreduce.lib.input.FileInputFormat;
import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;
public class WordCountDriver {
	public static void main(String[] args) throws IOException, ClassNotFoundException, InterruptedException {
		Configuration conf = new Configuration();
		Job job = Job.getInstance(conf);
		job.setJarByClass(WordCountDriver.class);
		job.setMapperClass(WordCountMapper.class);
		job.setReducerClass(WordCountReducer.class);
		job.setMapOutputKeyClass(Text.class);
		job.setMapOutputValueClass(IntWritable.class);
		job.setOutputKeyClass(Text.class);
		job.setOutputValueClass(IntWritable.class);
		FileInputFormat.setInputPaths(job, new Path(args[0]));
		FileOutputFormat.setOutputPath(job, new Path(args[1]));
		// 设置reduce端输出压缩开启
		FileOutputFormat.setCompressOutput(job, true);
		// 设置压缩的方式
	    FileOutputFormat.setOutputCompressorClass(job, BZip2Codec.class);
//	    FileOutputFormat.setOutputCompressorClass(job, GzipCodec.class);
//	    FileOutputFormat.setOutputCompressorClass(job, DefaultCodec.class);
		boolean result = job.waitForCompletion(true);
		System.exit(result?0:1);
	}
}
2)Mapper和Reducer保持不变
具体可以参考5.1中案例所示